Invoice Extraction Fails on the Template You Didn't Train On
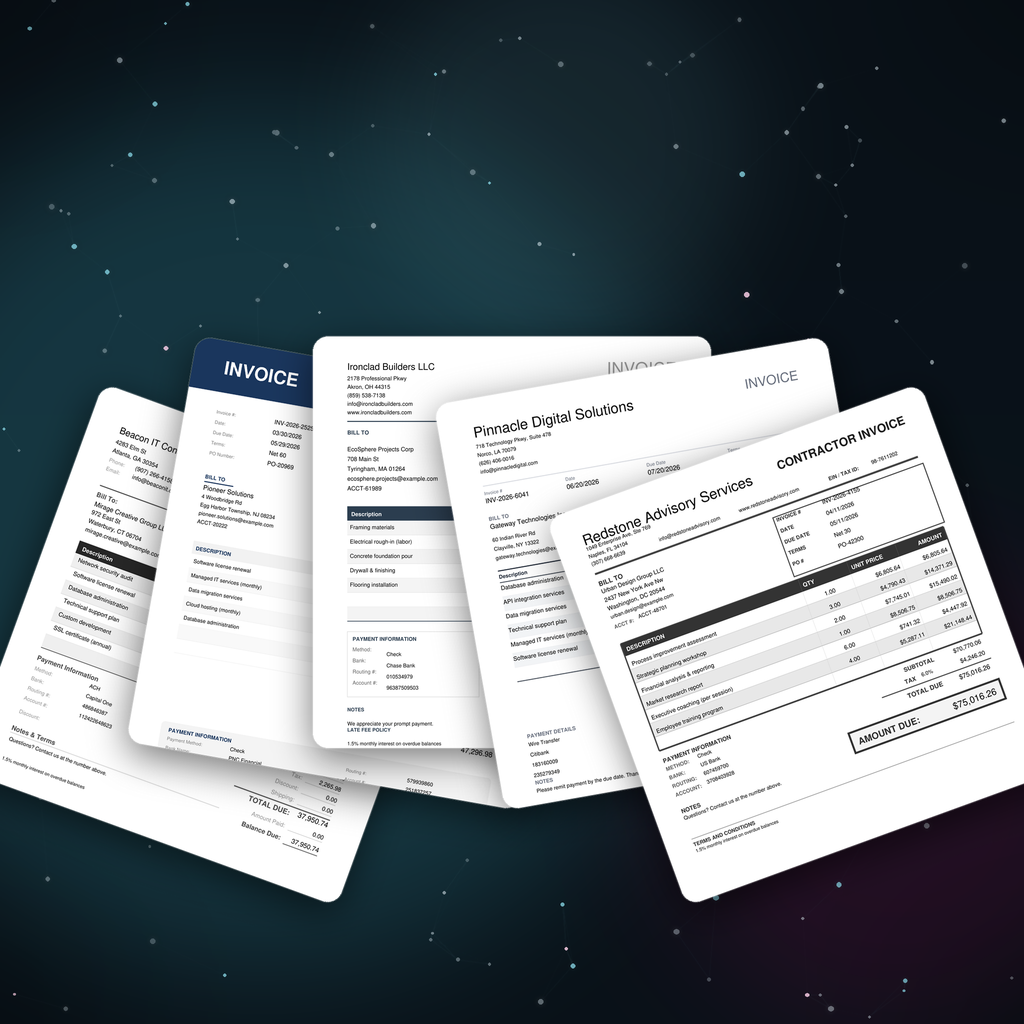
Invoice extraction breaks on templates it was not trained on. Train layout-invariant models with synthetic invoice data and a held-out-template eval.
Synthetic document data, OCR training, Document AI, and privacy-safe ML workflows.
Subscribe via RSS
Invoice extraction breaks on templates it was not trained on. Train layout-invariant models with synthetic invoice data and a held-out-template eval.

Install the SymageDocs SDK, generate labeled synthetic W-2s, and convert the FUNSD annotations into LayoutLMv3 training features. Runs on the free tier.

Your model hits 94% character accuracy on printed text and 61% on handwritten fields. This isn't a model architecture problem. It's a training data distribution problem — and once you see it clearly, the fix is straightforward.

A practical guide to how synthetic document data works, what makes it structurally different from anonymized or augmented real data, and when your ML pipeline actually needs it.

Random data generators like Faker produce independent field values with no structural coherence. Here's why that matters for document extraction models, and what to use instead.